The tire size mess

A guy asked me a while ago how to read the tire size codes in a wheel. After explaining him, he complained because his results did not match a measurement made on a real wheel. I´ll try to explain why:

205/55R16. What does this mean?

Well, don´t tell me why they did it, but the guys that decided how to code tire sizes made a complete mess around something, in theory, really simple: width, sidewall height and rim diameter. That´s all, but expressed in the most strange and disturbing units they were able to find. It could only be stranger if expressed tire width in light-years…

Tire width: expressed in millimeters. Everything fine by now. Just measure your tire´s width, from a top view, when no load is applied to it.

Tire sidewall height: expressed as a percent of the tire width. So, if the width is 205 mm, a 55% of that (the sidewall height) is 112.75 mm.

Rim diameter: expressed in inches. To translate:

  • inches to meters -> multiply by 0.0254
  • meters to inches –> divide by 0.0254

So, the rim´s diameter will be 406 mm in this case.

An easy calculation: wheel (tire+rim) diameter

If no stress is applied to the wheel, the diameter should be:

Wheel diameter = rim diameter + (sidewall height x 2)

It is important to note that the sidewall height should be multiplied by 2, as it´s the height of one side only (see next picture).

image

Why do I get different results if I measure my tire?

When you take a tape and go out to measure your car´s tires, you will see different results. Specifically in the tire´s sidewall and rim proportion. You should not find any differences in the wheel diameter or radius. Why´s that? Easy… because you are not doing it properly, and this mistake is seen in many places.

The rim diameter should be measured from the inner part where that the tire bead sits on, not from the exterior visible part. So, in order to properly measure the rim size, you will have to take the tire off the rim first, or make an estimation of the amount of tire sidewall that fits inside the rim (usually a bit more than 2 cm, or a bit less that 1 inch).

image

So, measured from the exterior part, with the wheel mounted, we will get at rim (more or less) 2 cm bigger (and of course, 2 cm less of sidewall height).

To know more about tires: The wheel and tire bible

Contribution to SlimDX. UVAtlas wrapper

If you are a .Net developer who wants to deal with 3D Graphics, your best two options are:

  1. Go the XNA way
  2. Use SlimDX 

As all of you probably already know, XNA is a .Net full framework for Game Development. It´s very easy to use, powerful, and cross-platform with the XBox and Zune (too bad no support for Windows Mobile yet). It is great, but in some cases, it has its disadvantages, as being cross-platform introduces some limitations for windows only development.

SlimDX is a DirectX Wrapper to allow .Net developers access the DirectX functionality from C#, Visual Basic, IronPython, etc… It´s a bit more complex, as it just “translates” DirectX to .net, but it is currently the only way to get access to DirectX 10 and DirectX 11 from .Net.

Which way you choose is your business and should depend on many factors. Check the links for more information.

The point is that, due to the problems regarding UVAtlas in Managed DirectX 9 (depicted here), I constributed to the last release (March 2009) of SlimDX with a UVAtlas wrapper for DirectX9, a feature still not present in SlimDX. This implementation fixes the problems present in MDX and explains a bit the meaning of some parameters.

Hope it helps someone.

D3DX UVAtlas for mesh parameterization fails with some meshes (Partition, Pack and Create)

I have been searching for a solution to this situation for a long time. Searched and searched with no luck on the net. I guess that not many people is using the UVAtlas functionality that comes with DirectX9. So, these are my findings:

Partition and Pack always fail?

If you are using the Managed version of DirectX, the Partition and Pack methods will ALWAYS fail. I´m not sure if it´s related to the MDX implementation itself or (as ZMan suggested), may be due to MDX being based on an old version of DirectX. However, if you want to use them, you will have to deal with the native version: D3DXUVAtlasPartition and D3DXUVAtlasPack.

If you have been experiencing random failures in the UVAtlas generation, keep reading:

I have found that the problem is related to the MaxStretch parameter. If you don´t care much about stretching your geometry in the Atlas, the reasonable value is "1" (any amount of stretch allowed), but this value will cause errors with some meshes. I still wasn´t able to detect why and when it fails exactly.

More precisely, what happens then is that Partition method returns wrong values as output texture coordinates, even when returning S_OK as result. If you don´t detect this situation (as D3DXUVAtlasCreate doesn´t) and pass the resulting wrong mesh to the Pack method, it will throw an exception. The worst thing is that this exception is sometimes a native memory violation exception, so a managed try-catch won´t handle it and will force your application to exit.

To detect wrong texture information, Lock the mesh VertexBuffer (to get into its contents) and check for wrong resulting U,V values: +/- infinity, NaN, or extremely big values.

The general criteria to fix this situations is to low MaxStretch down. Most of the times (if not always), using 0.999f instead of 1 makes it, but maybe sometimes you will have to make it even lower, depending on your meshes.

Hope this helps.

Cheers!

How to sign C++ CLI assemblies with a strong name

If your application is signed with a strong name, Visual Studio will require you to sign every assembly you reference. Now, even if you are a .Net only developer, it happens sometimes that you have to deal with some kind of interop with C++/CLI DLLs. If both situations happen, you will find yourself in the need to sign a C++ assembly with a strong name.
To do so, you have to specify the key file you will use at:
Project->Properties->Configuration Properties->Linker->Advanced->Key File. Something like this:
image
Don´t try to sign the assembly with a .Pfx file. It won´t work. To do so, you need a .SNK file (Strong Name Key). You can generate one with the SN.EXE tool, using:
sn.exe –k [directory]\[filename].snk
Where to find SN.EXE ?
In the Microsoft .Net Framework SDK (usually c:\program files\microsoft .net\sdk\bin, or something similar). You can download the SDK from here.
Note: In order to install that SDK, you will also need the .Net Framework 1.1 installed. As it´s a bit old, many people don´t have it in their machines.

Avoid that strange “Form going to background” effect in WinForms

Someone asked me yesterday about a strange effect he was getting in a WinForms application.

Scenario:

  1. Form1 is the main form of the application
  2. Form2 is a child form shown sometimes to make additional operations. This form is shown using the Show() method, not the ShowDialog() method. I´m not sure if this affects this specific situation, but in his program, Form2 is forced to never be closed (except when app exiting), so it can be reopened whenever the user wants, without loosing information. This way, when user closes the form, it´s in fact being hidden, not closed.

Symptoms:

Apparently sometimes, when user closes Form2 (actually hides it), the focus doesn´t come back to the main form. Instead, Form1 is minimized, what is very frustrating from the user experience point of view.

Solution:

What looked like a random behavior, it is in fact due to Form2 opening additional modal dialogs, like MessageBoxes, and setting their owner to himself (Form2). Something like this:

class Form2

{

…

MessageBox.Show(this, “Hello”, “World”…);

…

}

The solution is to set the MessageBox´s Owner to Form1 (the main form), instead of Form2, like this:

MessageBox.Show(this.Owner, “Hello”, “World”…);

And that´s it ;)

ListView highlighting effects (and how to force it to keep highlight when lost focus)


Many people ask about how to force a List View to keep the selected item highlight when the control lost its focus.

The obvious and fast answer is: Set “HideSelection” property to false, as it seems to be designed with such purpose. In part, this is true, because when the the list view losses the focus the item remains highlighted, but with the “inactive” color, instead the default highlight one.

A VERY EASY way to achieve is:

1.- Mark your list view as “Owner Draw” (OwnerDraw property = true)

2.- Write an event handler for the even “DrawItem” or “DrawSubItem” of the list view, doing something like this:


private void lvModelsInfo_DrawItem(object sender, DrawListViewItemEventArgs e)
       {
           if (e.Item.Selected)
           {
               e.Graphics.FillRectangle(new SolidBrush(COLOR1), e.Bounds);
               e.Graphics.DrawString(e.Item.Text, listview1.Font, COLOR2, e.Bounds.Location);
           }
           else
           {
               e.Graphics.DrawString(e.Item.Text, listview1.Font, COLOR3, e.Bounds.Location);
           }
       }


Et´voila. The list view keeps the highlight.

In addition to that, I´ve marked three variables: COLOR1, COLOR2 AND COLOR3. This vars allow you to customize the selection highlight color, item fore color (when selected), and item fore color (when not selected), respectively.

Hope this helps.

Cheers!

Bungie´s Lighting and Rendering pipeline

Yesterday, I found a very interesting website with publications and articles from Bungie, the creators of Halo. You can find them here.

One of them talks about lighting and rendering and there is a specially interesting slide that will explain a lot of people how they achieve such a wonderful visuals. It shows, step by step, the rendering stages they process (which doesn't necessarily have to be done in different passes). Starting from the transformed geometry:

1.- Draw geometry with shaders using the following information:

  • Albedo (on the right): This includes normal textures, taken form pictures and processed to be seamless, normalized lighting, etc.
  • Normal Maps (on the left): Special textures storing surface information, instead of visual appearance or color.

One thing to note: Watching the albedo, they don´t use HDR textures. This is something logical, as it frees content creators form processing every single texture to adapt it to scene lighting conditions. This ifnormation is applied in the next step.

image

2.- Static Lighting

Applies lighting calculations from static lights. This process is probably the responsible to add the HDR information to the result of the previous stage. You can clearly appreciate it in the following picure (the level of contrast between the outside and inside parts is huge).

image

3.- Dynamic Lights

This stage adds the lighting information coming from lights that may change each frame (moving or changing lights, etc). In the picture, you can clearly see the new light that will simulate an explosion later. Of course, this light needs to be dynamic, as it´s intensity will vary to simulate the explosion effect.

image

4.- Transparents

To achieve some visual effects, like lens flares, explosions, fire, etc, using 2D impostors is still the way to go. You can appreciate the ray or explosion effect in the picture.

image

5.- Post-processing

And finally, with some 2d post processing (some bloom, tone mapping, etc), and the final result.

image

Microsoft Research and Bungie… talented people, for sure…

image

Howto hide properties and methods to Intellisense


Has happened to you, that you know a method or property exists in a class, but the Intellisense doesn´t show it up? This happens sometimes with some classes in Windows.Forms.

I can tell you that it´s sometimes useful to hide a property or a method to Intellisense, although it´s still there for compilation. Imagine for example that you have a property for design time purposes only, but the member variable it gives access to is still public for performance reasons. In this case, it could be a good idea to hide it from Intellisense, so it´s not offered as the recommended way of accessing that data. In addition to that, you avoid having two entries in the Intellisense window for the same data, so it remains cleaner.

How to achieve that? Easy, using the System.ComponentModel namesmace. Just add this attribute to your property or method:

[EditorBrowsable(EditorBrowsableState.Never)]

There´s only one limitation to this attribute that seems to be impossible to override: It will only work OUTSIDE your project. I mean, inside the same DLL of your property, it will still be shown by Intellisense. Even in other projects that use your DLL, if they directly reference the project as a project-project reference (both projects inside the solution), the property will still be shown.

Although I don´t like this (it would be better if you could choose to even switch off this behavior too) this is intentional, because Intellisense understands your are the owner of the DLL and that you are in “development mode” on those cases.

You can read more information here.

Programación paralela y Processor Affinity. Nunca subestimes el Scheduler de Windows Vista


El gran Maligno ha subido mi post sobre Parallel Computing and Processor Affinity  al blog www.windowstecnico.com, más concretamente aqui. Como en ese blog traducen todos los posts, Matias Cordero ha sido tan amable de traducir el mío al Español, así que lo incluyo también aqui por si alguien prefiere leerlo en Castellano.

Traducción por: Matías Cordero

Translated by: Matías Cordero (you can read the english version here).

Todo el mundo sabe que la paralelización es una tarea importante pero dura, y parece que no va a ser posible incrementar mucho mas las velocidades de reloj de las CPUs. El futuro es multicore! Así que toca ponerse con System.Threading ya mismo.


Determinar el balanceo apropiado

Cuando identificamos una tarea paralelizable, siempre es complicado encontrar el balanceo apropiado para la paralelización. ¿Es mejor abrir mas hilos o es mejor darle mas trabajo a cada hilo? La respuesta a esta pregunta depende, por supuesto, de muchas cosas, y sobre todo en la naturaleza de la tarea que gestionará cada hilo.

Es importante averiguar la cantidad de tiempo que la tarea va a estar “ociosa” en cada hilo. Si es una tarea intensiva, entonces es mejor iniciar menos hilos con mas trabajo en cada uno. Si es al contrario (una tarea que tiene muchos “parones” esperando por algo –IO, gráficos, lo que sea-), entonces es mejor abrir muchos hilos con poco trabajo, porque se distribuirán entre los núcleos físicos de la maquina cuando uno este “parado”. Por supuesto, nunca hay que abrir menos hilos que los cores físicos de la máquina.

¿Cuál es el objetivo? El mismo que en los hoteles… 100% de ocupación.

Una manera fácil de determinar la naturaleza de nuestra tarea es dejarla correr en una única CPU, y mirar el grafico de uso de la CPU del Administrador de Tareas. Esto nos dará una idea de el uso de CPU que ha realizado el proceso. Os preguntaréis ahora como forzamos a nuestra aplicación para que se ejecute en una CPU específica. La respuesta es Afinidad del Procesador o Processor Affinity (ver abajo).


Perder, o no perder el control. Esa es la cuestión…

Cuando comienzas por primera vez a pelearte con la paralelización, la primera idea es separar los procesos por las CPUs tu mismo. ¿Por qué no? Si tienes 10.000 operaciones, abre cuatro hilos con 25.000 operaciones cada uno. El primero para la CPU0, el segundo para la CPU1, y así sucesivamente… Yo me siento muy cómodo con esta idea. Dicho y hecho, y todo bajo control, ¿no? Bueno, no siempre es tan sencillo.

En un mundo ideal, una tarea simple, que no va a ser paralelizada más y que vive solita (no con las docenas de vecinos que un proceso tiene en un SO moderno), se gestiona mejor con una sola CPU, porque esto incrementa los aciertos de cache y elimina el consumo de la infraestructura de cambio entre hilos. Pero en la vida real, los procesos son interrumpidos por las operaciones del sistema, IO, otros procesos y muchas otras cosas. Una maquina multi-núcleo es perfecta para manejar todas esas interrupciones, porque puede repartirlas por los núcleos existentes, pero si comenzamos a fijar nuestras aplicaciones a CPUs específicas, la capacidad del sistema para evitar bloqueos y esperas se reduce considerablemente.

Como explica este gran artículo, la mayoría de las veces, es mucho mejor delegar en el Sistema Operativo para que pueda poner cada hilo donde el quiera. De todas maneras, veremos algunos resultados que avalan esta decisión mas tarde.

Processor Affinity de un proceso

En Windows, podemos forzar un proceso para que se ejecute en una CPU específica simplemente utilizando el Administrador de Tareas (botón derecho sobre el proceso y seleccionar “Establecer Afinidad”) o programáticamente utilizando el espacio de nombres System.Diagnostics. La siguiente línea cambiará la afinidad del proceso actual a la CPU1:

System.Diagnostics.Process.GetCurrentProcess().ProcessorAffinity = (System.IntPtr)1;

La propiedad ProcessorAffinity es una máscara de bits variable. Los valores son:


Valor

Procesadores permitidos

0 (0000)

No permitido (significa no utilizar procesadores)

1 (0001)

Procesador 1

2 (0010)

Procesador 2

3 (0011)

Procesadores 1 y 2

4 (0100)

Procesador 3

5 (0101)

Procesadores 3 y 1

6 (0110)

Procesadores 3 y 2

7 (0111)

Procesadores 3, 2 y 1

8 (1000)

Procesador 4


y así sucesivamente…

Tened en cuenta que esto cambiará la afinidad del proceso actual (la aplicación completa), no del hilo actual. Cualquier hilo que se haya abierto desde este proceso heredará la misma afinidad.

Processor Affinity de un hilo.

El primer requisito para controlar como se distribuyen tus hilos entre las CPUs es ser capaz de establecer la afinidad con el procesador de un hilo (no del proceso). Hay un post interesante sobre este tema aquí, donde Tamir Khason lo explica todo. Para cambiar la afinidad de un hilo debemos utilizar la clase System.Diagnostics.ProcessThread (propiedad ProcessAffinity). El problema viene cuando tratamos de averiguar que hilo es el que estamos buscando, in la lista de los hilos del proceso actual.

1.- Primera aproximación - Obsoleta

Conseguimos la instancia del ProcessThread con el siguiente código:

ProcessThread t = Process.GetCurrentProcess().Threads.OfType<ProcessThread>().Single(pt => pt.Id == AppDomain.GetCurrentThreadId());
t.ProcessorAffinity = (IntPtr)(int)cpuID;

El problema de esta aproximación es que el método GetCurrentThreadId está obsoleto, así que mejor no utilizarlo.

2.- Segunda aproximación – No válida

Podéis estar tentados de utilizar la propiedad ManagedThreadID para buscar dentro de la colección Threads del proceso. No lo hagáis. ProcessThread.ID no tiene nada que ver con la propiedad ManagedThreadID, representan cosas diferentes. Un tipo dice aquí que ManagedThreadID es de hecho el desplazamiento dentro de la colección ProcessThread, pero no he investigado mucho más, y no os aconsejo utilizarlo hasta que no verifiquéis esta información.

3.- Tercera aproximación – Válida, pero nativa (no manejada)

La tercer aproximación hace un “dllimport” del “kernel32.dll” y utiliza algunas de sus funciones. Este método está probado y funciona correctamente:

[DllImport("kernel32.dll")] 
static extern IntPtr GetCurrentThread();

[DllImport("kernel32.dll")] 
static extern IntPtr SetThreadAffinityMask(IntPtr hThread, IntPtr dwThreadAffinityMask);

SetThreadAffinityMask(GetCurrentThread(), new IntPtr(1 << (int)cpuID));

Una nota curiosa:

Si estáis programando para la XBox360 con XNA Game Studio 3.0, tenéis un método Thread.SetProcessorAffinity listo para utilizar, sin toda la morralla de arriba. Esto se debe a que la XBox necesita especialmente aprovecharse de sus núcleos para ofrecer un rendimiento decente. No se si la presencia de este método se debe a que el rendimiento del Scheduler de la XBox es peor que el de Vista… puede ser. De todas formas podéis leer mas aquí.


El Test

Tarea: Generar tres tablas 2D con resultados de un test geométrico en una escena 3D, incluyendo 975.065 pruebas de colisión (ray-mesh) cada una.

Hardware: Dell XPS 630 QuadCore

Software de monitorización: Process Explorer

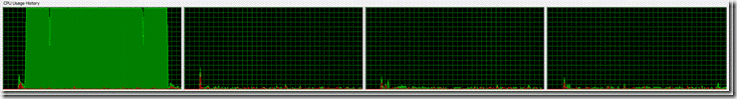
PARTE 1 (multihilo deshabilitado). Impacto de la afinidad del procesador

Test 1:

  • Número de hilos: 1 (hilo principal)
  • Afinidad con el procesador: CPU 1
  • Tiempo total: 2 min 57.11 seg

clip_image002

Con la afinidad con el procesador asociado a la CPU 1, todo el trabajo es obviamente gestionado por esta CPU. Los dos picos que se pueden apreciar en el gráfico se deben a operaciones de IO (guardar en disco) y marcan claramente la generación de cada tabla de datos. En esta prueba podemos observar claramente que nuestra tarea es muy intensiva y constante, porque mantiene el procesador al 100% de uso la mayoría del tiempo.

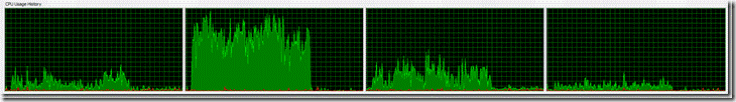
Test 2:

  • Número de hilos: 1 (hilo principal)
  • Afinidad con el procesador: Ninguna (cualquier procesador)
  • Tiempo total: 2 min 29.45 seg

clip_image004

La mayoría del trabajo se ha gestionado por la CPU2 pero el resto de los núcleos también han trabajado en el proceso (comprobado en Process Explorer que todas las líneas verdes pertenecen al proceso que se está midiendo). Está claro que forzar el proceso a trabajar únicamente en la CPU1 solamente introdujo bloqueos y periodos de espera, probablemente debido a interrupciones que venían de otros programas que también necesitaban la CPU1.

Ganador de la parte 1 ………  Windows Scheduler !

PARTE 2 (multihilo habilitado 1)

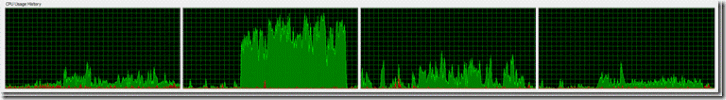
Test 1:

  • Número de hilos: 2 (hilo principal + 1 hilo de cálculo)
  • Afinidad con el procesador:
    • Hilo principal: Cualquiera
    • Hilo de cálculo: CPU 1
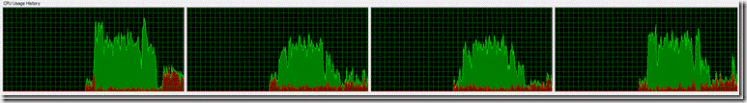
  • Tiempo total: 2 min 18.14 seg

clip_image006

Los resultados que obtenemos aquí son muy lógicos. El cambio principal en esta prueba es que estamos separando el cálculo de la actualización de la interfaz y el guardado en disco. Podéis apreciar los picos bajos en el primer gráfico y sus equivalentes en los núcleos 2 y 3 (donde se ejecuta la operación de guardado). Es muy interesante notar que separar las operaciones de salvado a núcleos diferentes no ahorra mucho tiempo, porque esperamos a que se completen antes de continuar con la siguiente tabla de datos. Por este motivo los picos bajos en el primer gráfico son mucho mas notorios. Hemos movido el procesamiento de un núcleo a otro, pero no hemos paralelizado nada.

De todas maneras notamos una leve mejora en el rendimiento, mayormente porque la actualización de la interfaz (que incluye manipulación de mapas de bits) se hace en los núcleos 2 y 3.

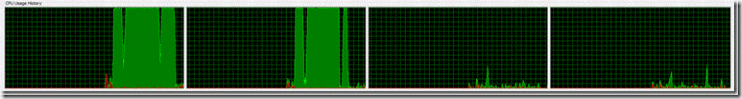
Test 2:

  • Número de hilos: 2 (hilo principal + 1 hilo de cálculo)
  • Afinidad con el procesador: Ninguna
  • Tiempo total: 2 min 14.86 seg

clip_image008

Esta vez podemos apreciar de nuevo que el trabajo se distribuye en todos los núcleos, con una más que remarcable presencia de la CPU2. De nuevo el scheduler de Windows gana la carrera.

Ganador de la parte 2 ………  Windows Scheduler !

PARTE 3 (multihilo habilitado 2)

Test 1:

  • Número de hilos: 3 (hilo principal + 2 hilos de cálculo)
  • Afinidad con el procesador:
    • Hilo principal: Cualquiera
    • Hilos de cálculo: CPUs 1 y 2
  • Tiempo total: 1 min 18.66 seg

clip_image010

Empezamos a ver una gran mejora en el rendimiento. El doble de poder computacional, casi el doble de rápido. Parece muy realista.

Test 2:

  • Número de hilos: 3 (hilo principal + 2 hilos de cálculo)
  • Afinidad con el procesador: Ninguna
  • Tiempo total: 1 min 16.59 seg

clip_image012

Otra victoria para el scheduler de Windows. obviamente cuando el tiempo total se acorta, las diferencias también lo hacen, pero el SO vuelve a ganar.

Ganador de la parte 3 ………  Windows Scheduler !

PARTE 4 (multihilo habilitado 3)

Test 1:

  • Número de hilos: 5 (hilo principal + 4 hilos de cálculo)
  • Afinidad con el procesador:
    • Hilo principal: Cualquiera
    • Hilos de cálculo: CPUs 1, 2, 3 y 4
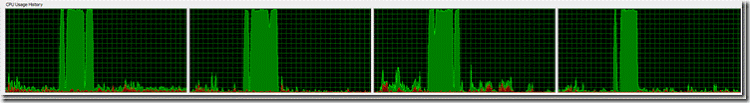
  • Tiempo total: 41.76 seg

clip_image014

Ahora viene el gran aumento del rendimiento. Con 4 hilos de cálculo, el tiempo total se reduce a 41 segundos! Veamos  como se comporta el SO con 5 hilos.

Test 2:

  • Número de hilos: 5 (hilo principal + 4 hilos de cálculo)
  • Afinidad con el procesador: Ninguna
  • Tiempo total: 42.05 seg

clip_image016

Wow… Ha estado muy cerca! Esta vez el SO pierde.

Ganador de la parte 4 ………  Afinidad con el procesador! (estuvo cerca)

PARTE 5 (multihilo habilitado 4)

Test 1:

  • Número de hilos: 9 (hilo principal + 8 hilos de cálculo)
  • Afinidad con el procesador:
    • Hilo principal: Cualquiera
    • Hilos de cálculo 1..4: CPUs 1..4
    • Hilos de cálculo 5..8: CPUs 1..4
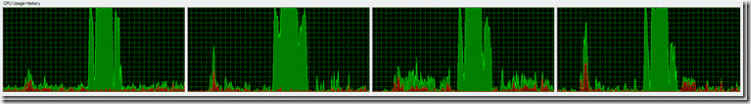
  • Tiempo total: 41.07 seg

clip_image018

Test 2:

  • Número de hilos: 9 (hilo principal + 8 hilos de cálculo)
  • Afinidad con el procesador: Ninguna
  • Tiempo total: 38.24 seg

clip_image020

Wow… ese es mi chico! 38 segundos !!!

De todas maneras, estos son resultados esperados. Si establecemos más hilos que núcleos físicos, es obvio que debemos hacer alguna programación de hilos. Forzando los hilos a trabajar en una CPU concreta simplemente reduce la paralelización. Como se puede ver no obtenemos beneficio alguno cuando usamos 8 hilos de cálculo  en lugar de 4 (con la afinidad habilitada). Por lo tanto queda claro que dejarle libertad a Windows en este caso, simplemente hacer su trabajo, es de lejos la mejor opción.

Ganador de la parte 5 ………  Windows Scheduler !

Resultados

clip_image021

Test

Vista Scheduler (seg)

Processor Affinity (seg)

Parte 1

149.45

177.11

Parte 2

134.86

138.14

Parte 3

76.59

78.66

Parte 4

42.05

41.76

Parte 5

38.24

41.07


A sí que ¿cuál es el número óptimo de hilos para mi tarea?

¿Continuará esta tendencia (cuantos mas hilos, mas rendimiento) para siempre? La respuesta es, obviamente, no.

En una tarea ideal, intensiva al 100% y constante, el número optimo de hilos sería el número de núcleos físicos, pero en la vida real, esa tarea tan intensiva es muy dificil de encontrar. La mayoría de los algoritmos de computación tienen tiempos de parada, esperando por una paginación de memoria, o similar. Así que, el número de hilos que te darán el mejor rendimiento dependerá de lo intensiva y constante que sea tu aplicación.

He medido algunos tiempos adicionales (para el scheduler del SO solamente):

    • 16 hilos –> 37.89 seg.
    • 18 hilos –> 37.44 seg.
    • 24 hilos –> 38.03 seg.

Así, para esta tarea parece que acaba en 18 hilos. Deberéis hacer vuestros propios tests para encontrar el número optimo de hilos de vuestros algoritmos. De cualquier modo, hemos probado que incluso en una tarea intensiva como esta, el número optimo de hilos, parece estar en torno a 18 para una máquina de cuatro núcleos, que significa 4 veces el número de núcleos fisicos!


Conclusiones

1.- El Windows Scheduler hace un GRAN trabajo (especialmente en vista). Bate una configuración manual en la mayoría de los casos, y en los que pierde, es por muy poco.

2.- Incluso si el SO fuera un poco peor en todos los casos, sería aconsejable utilizarlo, mayormente porque es automático y o tenemos que preocuparnos de la situación de los hilos.

3.- La afinidad con el procesador es uno de los mas importantes obstáculos en el paralelismo, así que utilizadlo sólo si lo necesitáis, no porque sois mas listos que Vista. En otras palabras: no reinventéis la rueda.  Confiad en el sistema operativo.

4.- Windows Vista Scheduler Rocks ! (esto no lo traduzco)


¿Para que se ha utilizado toda esta información?

Casi un millón de intersecciones de ray-mesh testeadas, y ¿a que se debe todo esto? La gente en España suele decir que si es blanco y viene en una botella, probablemente sea leche (nota del traductor: blanco y en botella).

Test masivos de intersecciones Ray-Mesh + Resultados almacenados como tabla 2D = Probablemente cálculos de luces.

Estos son los resultados, espero que os gusten.

clip_image022

Cuidaros!

Photoshop LensFlare filter and it´s small window with no zoom

1In Photoshop, it seems there´s no way to zoom your picture in the too-small window of the LensFlare Filter. This is something annoying if you are trying to place a LensFlare in a specific point of a big picture, as you have absolutely no accuray in the placing point. Just an example:

Imaging you want to process the image on your left, a picture of the most spectacular beauty in the motor vehicle industry ;). The objective is to add the Audi LED Lights effect, using the LensFlare filter. You open the LensFlare window up, and you find something like this:

4

There´s no single way to add the lens flare, one by one, with enough precission, as you cannot zoom in that window. So here is a simple way of fixing this:

1.- Activate the “Info” window, set your rulers to use “Pixels” as units, and keep the coordinates of the specific point where you want to add the LensEffect

2 2.- Go back to the LensFlare filter window, and use “Alt + click” instead of a simple click. A new window will appear where you can specify the lens flare coords. Et voilá, flare placed.


Maybe this second approach is even more useful:

1.- Create a new layer and paint it all black. Add the new lens flare in that layer, wherever you want.

2.- Change the kind of layer from “Normal” to “Screen”, so our lensflare is correctly blended with your background

3.- Now you can move and scale your lensflare as desired. You can even adjust it´s colors, exposure, brightness and contrast, everything.


This is the result of working this way:


3

Grata visita la de aquel día…

Ayer a media mañana, suena el teléfono. El Señor del Averno, a.k.a, Maligno al otro lado de la línea, anunciando que había venido por tierras Navarras.

La verdad es que estoy en las nancias, porque ni me había enterado del evento. Resulta que venía con Fernando Guillot, Paulo Dias y más gente en su gira de seguridad, y yo con estos pelos. Por cierto, mis enhorabuenas a Rafael Flores por la co-organización del evento (a través de CES Navarra), ya que por lo que pude ver fué un éxito de participación.

También tuve oportunidad de conocer en persona a Asier Marqués, crack del desarrollo web y que ya había escrito algo sobre Simax aqui. En fin, que nos tomamos un café muy “agustico” y luego nos pasamos por las instalaciones de Simax, para que se viciaran un poco con los simuladores. Esta foto da buena cuenta de ello…

SNC00009

Control your Vibrator from C#

And I´m talking about your Phone´s vibrator. What you were thinking of? ;)

I usually play around with Windows Mobile development through the Compact Framework. In my spare time, I´m working in a new project which requires to control the phone´s vibrator. As I had to look for a while to find a solution, I´m posting here what I found.

  1. Download the latest free version of the amazing OPENNETCF from here.
  2. If you are using a Smart Phone, use the Vibrate class found at the OpenNETCF.WindowsCE.Forms namespace. It works just as a Play/Stop static class, so nothing else needed to be explained.
  3. If you are using a Pocket PC, you will have to do it in a different way:

For Pocket PCs, the vibration feature is implemented as a notification LED. You can get access to the vibrator or any other LED of your device with the LED class found at the OpenNETCF.WindowsCE.Forms namespace. The drawback is that you will have to find yourself which LED is actually mapped to the vibrator, as it seems there is no way to find that programmatically. The process to use the vibrator is simple:

3.1.- Create the class that will give you acces to the LEDs:

                OpenNETCF.WindowsCE.Forms.Led leds = new OpenNETCF.WindowsCE.Forms.Led();

3.2.- The Count property of object “leds” will tell you how many leds your device has, but nothing else. You can test with all of them until you find the vibrator.

3.3.- Once you have the LED index mapped to your vibrator (assuming it´s at index 1), you can activate or deactivate the vibrator using:

                 leds.SetLedStatus(1, OpenNETCF.WindowsCE.Forms.Led.LedState.On / Off);

AFAIK, each device may have it´s vibrator mapped to a different LED index. Here is the list of LED indices I know:

  • HTC Touch / Elf / Himalaya (and probably most HTCs) … 1
  • Samsung i-900 / Omnia … 11

TODO

I don´t even know if this is possible (may be there´s no such hardware functionality), but it would be cool to control vibration intensity, so more complex feedback patterns could be output to the user. Anyone knows about this?